Open and Plot Parquet Files Online
Open, scroll and plot millions of Parquet rows directly in your browser. No upload.
Open a Parquet file
Drop it here or choose a file to see its schema and plot it. Millions of rows are fine.
No .parquet file to hand? The sample is ten years of made-up hourly UK weather.
Tip: drop several files to compare them.
Your file never leaves your device. It is read and charted by your browser. Nothing is uploaded.
- Available now:
- the schema and column statistics at once, every row in the table, sorting, filtering and searching the rows, charts of any column, and the whole file, the columns you pick or the table as shown as CSV.
- Coming soon:
- comparing two versions of a file by key.
At a glance
- Opens
- .parquet files from data pipelines and notebooks (pandas, pyarrow), with every common compression: Snappy, Gzip, Zstandard, Brotli and LZ4.
- Schema at once
- Each column’s name and type, its missing values, smallest and largest value, the row count and the row groups, as soon as you choose the file.
- Big files
- 10 million rows open and draw their first chart in about 1 second. Wide files with large text columns open fast too: those columns are read when you use them.Measured in Chrome on a recent laptop (Apple M4): a 141 MB Parquet file (Snappy) with 10,000,000 rows and 5 number columns, from choosing the file to the first chart. Slower devices take longer.
- Plots
- Line, step, bar, area and scatter charts, histograms and box plots of any column, with two y axes. Zoom with the scroll wheel, a pinch or a drag and the full detail reloads at once.
- Table and statistics
- Scroll every row, and read the count, missing values, min, max, mean, median, quartiles and standard deviation of any column.
- Export
- The whole file, or the columns you pick, as CSV on the Parquet to CSV page, and any chart as a PNG image.
- Processing
- Runs in your browser. Your .parquet file is never uploaded, and you need no Python.
- Price
- Free. No account or sign-up.
How to open a Parquet file online
- Open your .parquet file. Drop the file onto the viewer at the top of this page, or click “Choose a file”. Its schema, row count and column statistics appear at once, while the rows are read.
- Look at the schema. Click “Schema” in the file bar for every column’s type, missing values, smallest and largest value and size. The table below the chart scrolls through every row, and you can sort, filter and search it.
- Plot, zoom and compare. The first number column is plotted against the time column straight away. Tick more columns, put one on the right axis, zoom with the scroll wheel, a pinch or a drag, and read each column’s statistics in the side panel.
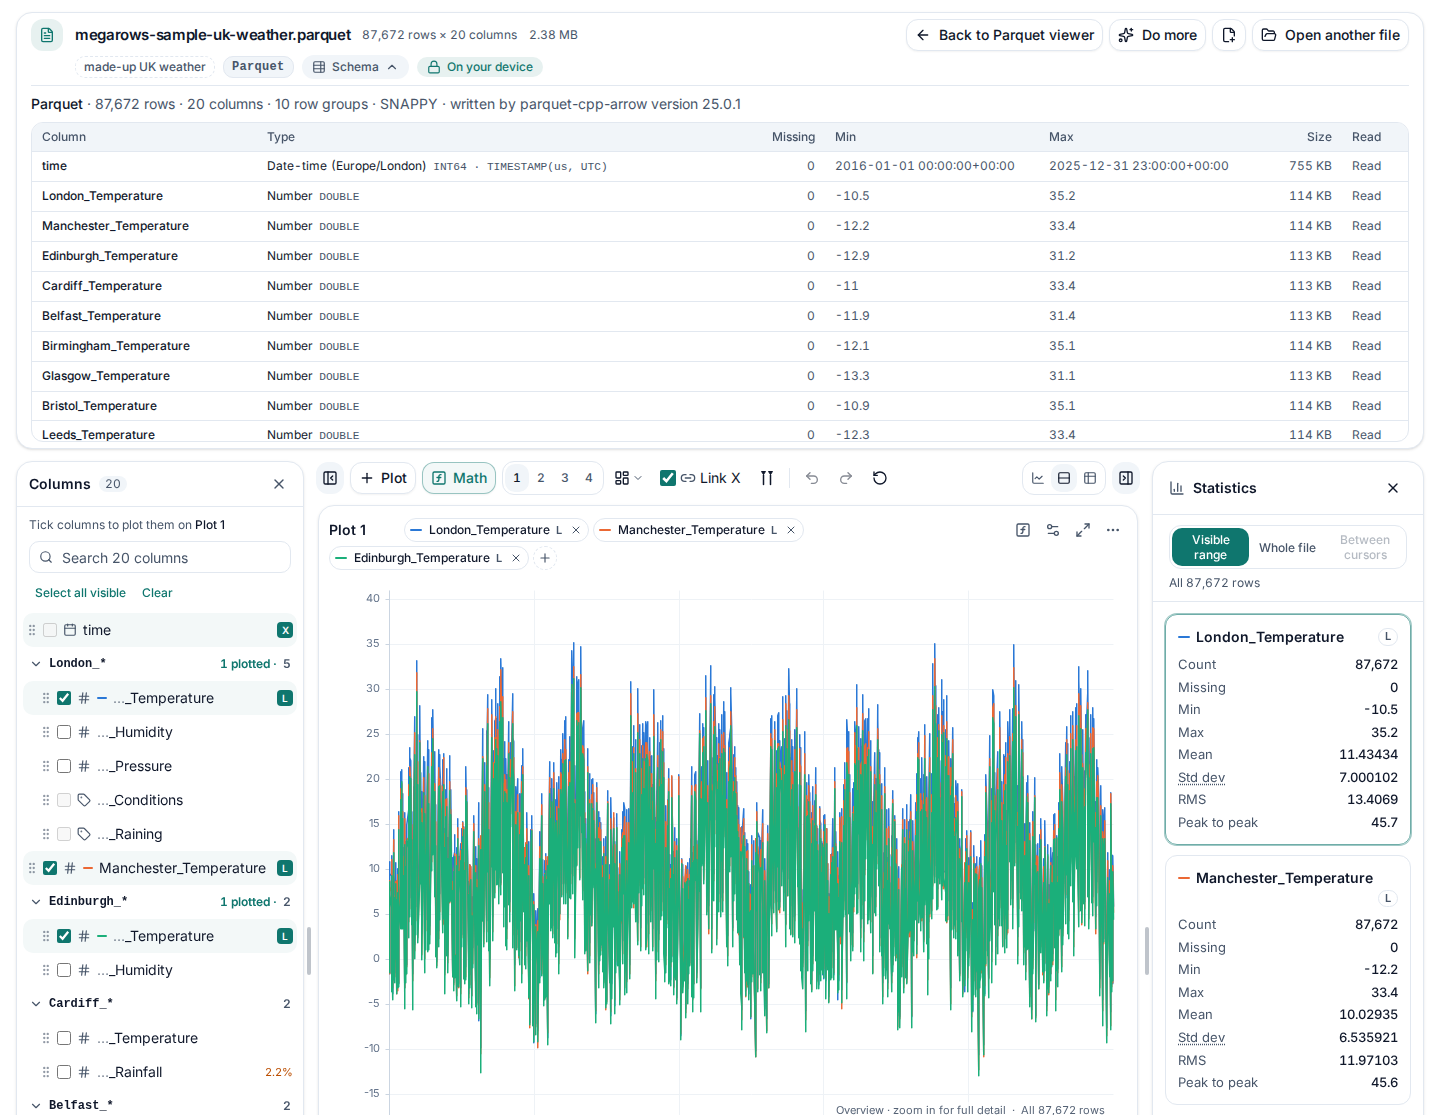
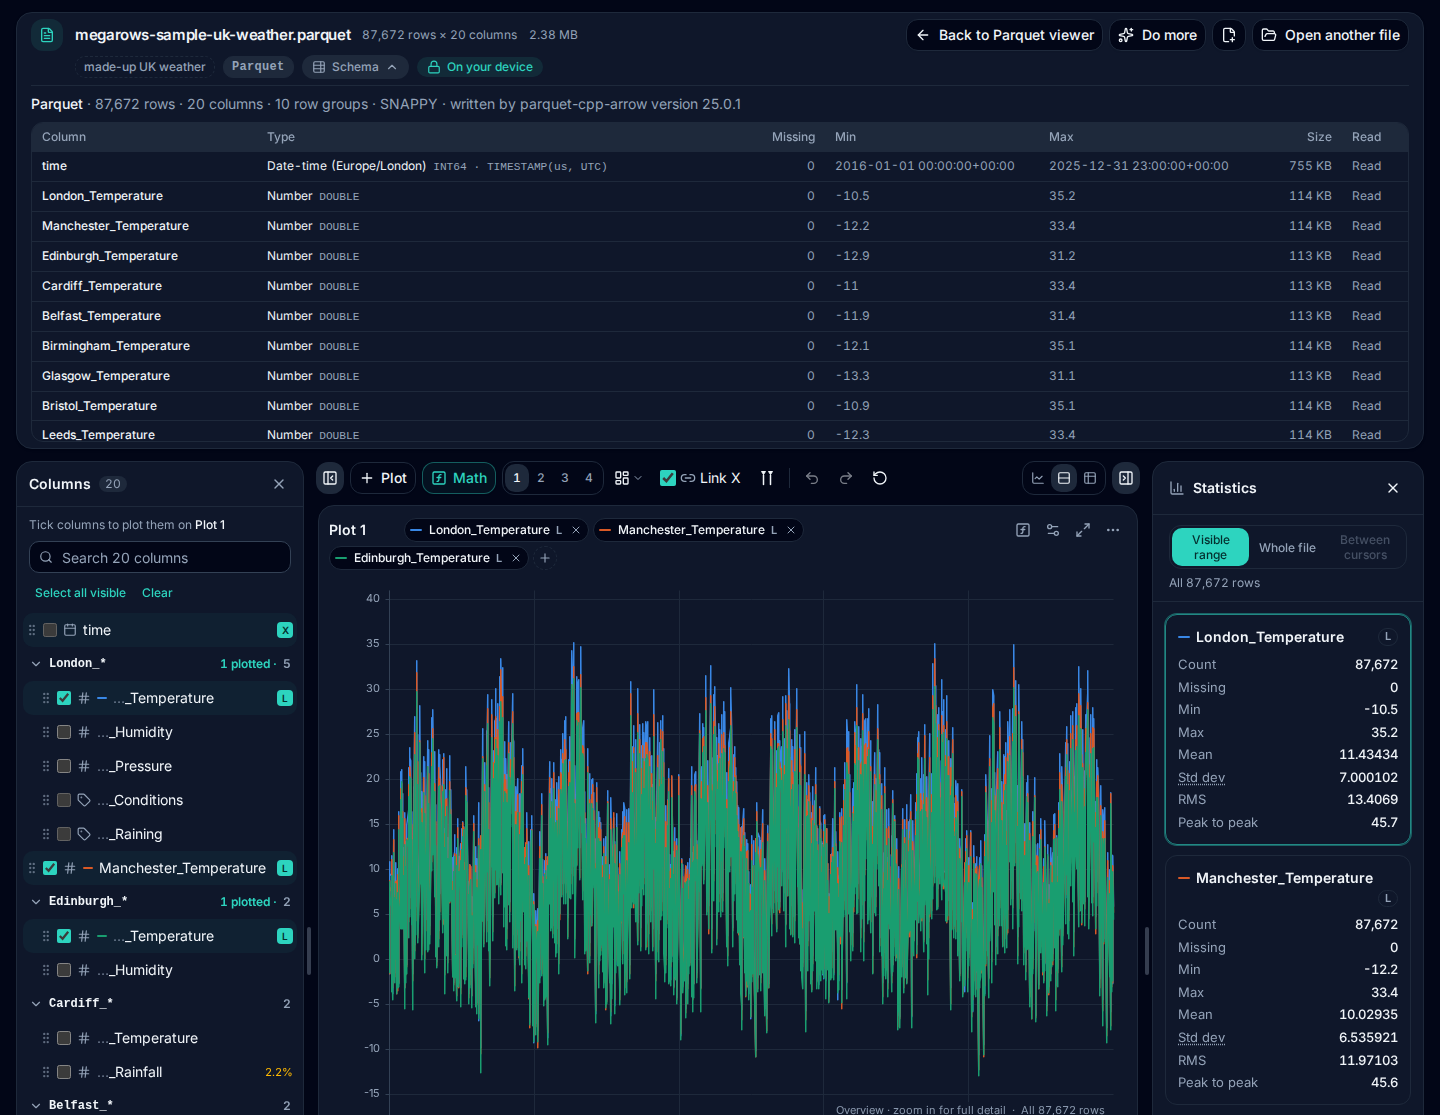
To try it in Python or another tool too, download the sample Parquet file.
Check this example
“Try a sample Parquet file” opens ten years of made-up hourly UK weather, with London_Temperature, Manchester_Temperature and Edinburgh_Temperature plotted against time. Click Schema in the file bar and it reads 87,672 rows · 20 columns · 10 row groups · SNAPPY, with these rows among the twenty:
| Column | Type | Missing | Min | Max |
|---|---|---|---|---|
| time | Date-time (Europe/London) | 0 | 2016-01-01 00:00:00+00:00 | 2025-12-31 23:00:00+00:00 |
| London_Temperature | Number (DOUBLE) | 0 | -10.5 | 35.2 |
| Cardiff_Rainfall | Number (DOUBLE) | 1,891 | 0 | 9.4 |
Tick Cardiff_Rainfall in the channel list to plot it as well: with the whole file in view, the Statistics panel gives it the same 1,891 missing hours, minimum and maximum, worked out from every row. Read on its own with pyarrow, the Python library for Parquet files, the file gives the same row count, row groups, missing values, minimums and maximums (checked with pyarrow 25.0.1 on 23 October 2026). A test opens the sample on every change to the site and checks that the schema and the Statistics panel show these numbers.
Plot Parquet data, not just read it
A Parquet file viewer that only shows a table tells you the values; a chart shows you what they do. This free Parquet viewer online is also a plotter: every number and date column can be charted, as a line, step, bar, area or scatter chart or a histogram, with a second y axis for a column in other units. Zoom into a moment with the scroll wheel, a pinch or a drag, and the full detail of that range reloads at once, so a one-sample spike in millions of rows stays visible. Add more charts side by side, summarise by month or by category, and save any chart as a PNG image.
A large Parquet viewer, built for big files
Parquet files from data pipelines are often too big for a spreadsheet and slow to open in a notebook. In our tests in Chrome on a recent laptop, a Parquet file with 10 million rows opened and drew its first chart in about 1 second*.
* Measured in Chrome on a recent laptop (Apple M4): a 141 MB Parquet file (Snappy) with 10,000,000 rows and 5 number columns, from choosing the file to the first chart. Slower devices take longer.
The machine, the browser and how we time a file are on how we measure speed.
Wide files open fast too: number, date and category columns are read with the file, and large text columns, such as free-text notes or IDs, are read the first time you plot them or ask for their statistics. The table shows them straight away. The notes say which columns those are, and “Schema” marks them.
A Parquet schema viewer
The schema is the first thing you see: as soon as you choose a file, the viewer lists every column with its Parquet type, the type it is shown as, its missing values, its smallest and largest value and its size, together with the row count, the row groups and the compression, all taken from the file itself. Afterwards, “Schema” in the file bar shows it again.
| In the Parquet file | Shown as |
|---|---|
| INT8 to INT64, unsigned too, FLOAT, DOUBLE, half floats | Numbers. 64-bit integers beyond about 9 quadrillion are rounded, with a note. |
| DECIMAL | Numbers, with a note when a value has more than 15 significant digits. |
| TIMESTAMP (ms, µs, ns), INT96, DATE | Dates and times, plotted on a time axis. A timestamp with its own time zone shows on that zone’s clock, with the offset; one stored in UTC without a zone shows in UTC. |
| TIME | Times of day (hh:mm:ss). |
| STRING, ENUM, JSON, UUID | Text, or categories when values repeat (ready for summaries by category). |
| BOOLEAN | The categories true and false. |
| Structs (also nested) | One column per field, named like station.name. |
| Missing values (nulls) | Empty cells and gaps in the chart. |
What isn’t supported yet
- Lists and maps. Columns that hold lists, maps or lists of structs are listed in the notes and the schema as not shown yet; the other columns open as usual.
- Binary data. Raw bytes, geometry and variant columns are listed but not shown.
- Encrypted files and LZO compression. Encrypted Parquet files and the rare LZO codec get a message saying so. Save the file again without encryption, or with Snappy or Zstandard.
- Editing and saving Parquet. The viewer reads .parquet files; it never changes them. To get a CSV, use Parquet to CSV.
Parquet to CSV
Need the data in Excel or another tool? Parquet to CSV converts a .parquet file in your browser: see the schema, tick the columns and download every row as CSV.
Private by design: nothing is uploaded
Parquet files often hold customer, sales or measurement data that must not leave your company. Online viewers that upload the file put a copy on someone else’s server. MegaRows does not: the viewer runs entirely in your browser, and the file and its name are never sent anywhere. Read the privacy statement for details.
View a Parquet file without Python
In Python, pandas.read_parquet("file.parquet") reads a file into a data frame, and plotting it takes a few more lines and a notebook. Command-line tools can print the schema. MegaRows needs none of that: open the Parquet file here, and the same viewer also opens CSV, Excel, JSON, MATLAB, HDF5 and LabVIEW TDMS files: see the CSV plotter.
Frequently asked questions
How do I view a Parquet file online without uploading it?
Open it in the viewer at the top of this page: your browser reads the file on your own device and never sends it to a server, so there is no upload and no upload size limit. You see the schema at once, then a chart and a table of every row.
Can I view a Parquet file without Python?
Yes. You do not need Python, pandas, a notebook or a command line: drop the .parquet file onto this page and it opens in your browser, with its schema, a chart and a table. Nothing is installed.
Which Parquet files can I open?
Files written by pandas, pyarrow and other Parquet writers, with Snappy, Gzip, Zstandard, Brotli or LZ4 compression or none. Numbers, decimals, dates, timestamps with or without a time zone, times, text, booleans and structs are shown; lists and maps are listed as not shown yet.
How large a Parquet file can I open?
As large as your device’s memory allows. In our tests in Chrome on a recent laptop, a 141 MB file with 10 million rows opened and drew its first chart in about 1 second. In wide files, large text columns are read when you plot them or ask for their statistics, so the file opens faster.
Can I see the schema of a Parquet file?
Yes. While the file opens, and afterwards from “Schema” in the file bar, the viewer lists every column with its Parquet type, the type it is shown as, its missing values, its smallest and largest value and its size in the file, plus the row count, row groups and compression.
Can I convert Parquet to CSV?
Yes, on the Parquet to CSV page: open the file, tick the columns you want and download every row as a CSV file, all in your browser. The plotter can also save the columns of a chart, for the rows in view, as CSV.
Why are some of my columns missing?
Columns that hold lists, maps, raw bytes or geometry cannot be shown yet. They are listed in the notes and in the schema as not shown yet, and every other column opens as usual. Fields of a struct are shown as their own columns, named like station.name.
Is my Parquet file uploaded anywhere?
No. The file is read by your browser on your own device, and neither the file nor its name is sent anywhere, which makes the viewer safe for confidential data. You can check it in the Network tab of your browser’s developer tools.
Related tools and guides
- CSV plotterOpen a CSV, Excel, TXT, JSON, MATLAB, Parquet, HDF5 or LabVIEW TDMS file with millions of rows and plot it in several linked charts, with zoom and statistics. Works today.
- Large CSV viewerOpen a CSV with millions of rows in your browser: scroll every row, see each column’s type and statistics, chart any column. Works today.
- MATLAB .mat file viewerOpen v4 to v7.3 .mat files without MATLAB and plot any signal. Works today.
- TDMS viewerOpen .tdms files from LabVIEW, DIAdem and DAQmx loggers: every group, channel and property, each channel plotted against its time. Works today.
- HDF5 viewerOpen .h5, .hdf5 and NetCDF-4 .nc files: every group, dataset and attribute, each group’s datasets plotted against their time. Works today.
- MAT to CSVConvert the signals of a .mat file, v4 to v7.3, to a CSV for Excel or Python, without MATLAB. Works today.
- Parquet to CSVConvert a .parquet file to CSV in your browser, with the columns you pick. Works today.
- TDMS to CSVConvert the channels of a .tdms file to CSV, a group at a time, with its time column, without LabVIEW or Excel add-ins. Works today.
- HDF5 to CSVConvert the datasets of an .h5 or NetCDF-4 file to CSV, a table at a time, with its time column, without Python. Works today.
- Excel to CSVConvert any sheet of an .xlsx or .xlsm workbook to CSV, with the saved results of formulas, real dates and 15 significant digits. Works today.
- JSON to CSVConvert JSON and JSON Lines files to CSV: nested fields become columns named by their path, arrays stay as JSON text. Works today.
- CSV to MATConvert a CSV, Excel, JSON or Parquet file to a MATLAB .mat file: a field per column, with names and units, every row. Works today.
- Merge CSV filesAppend many CSV files into one, even with different columns or separators. Works today.
- Split CSV filesSplit a CSV too big for Excel into parts of 1,000,000 rows, parts of a size you choose, or one file per value of a column. Works today.
- CSV row counterCount the lines in a CSV, TSV or TXT file of any size. Works today.
- CSV statisticsCount, missing values, min, max, mean, standard deviation, RMS and peak to peak of each number column, for the whole file or the rows you zoom into. Works today.
- CSV histogramA histogram of any number column, with automatic bins or 10 to 200 of them, and each bin’s count as a table. Works today.
- CSV too large for Excel?Open every row of a CSV beyond Excel’s 1,048,576-row limit, or work around the limit in six other ways.
- FFT and PSD from a CSVTurn a signal column into an FFT spectrum or a PSD with Grms, with results checked against SciPy. Works today.
- PSD calculatorTurn a vibration column into a power spectral density (Welch) in g²/Hz, with the Grms of any band and a dB view. Works today.
- Spectrogram from CSVSee how the frequencies of a measured signal change over time, as a heat map in dB, with the window and range you choose. Works today.
- FRF and coherencePick an input and an output column and get the frequency response (H1, H2, magnitude and phase) and their coherence. Works today.
- The MegaRows toolboxWhat works today and what is coming next, and why nothing is ever uploaded.
Coming soon to MegaRows: CSV to Excel and PDF reports · Compare CSV versions.
MegaRows processes files locally in your browser. Nothing is uploaded, not even the file name.